

Tenant Cloud
TCenter
Cloud Access Management
Ops Management Guide
Contingency Plan for Pod CPU Utilization (Relative to the Limit) Exceeding the Threshold
Contingency Plan for Pod CPU Utilization (Relative to the Limit) Exceeding the Threshold
Last Updated At: 2026-08-14 08:08:00

Alarm Description
Pod CPU utilization (relative to the limit) exceeds the threshold:
- Containers related to basic platform workload (cloud-tcenter): Due to certain abnormalities, CPU utilization becomes high, exceeding 95% of the configured limit.
- Containers related to audit log workload (t|ocloud-cloudaudit): Due to certain abnormalities, CPU utilization becomes high, exceeding 95% of the configured limit.
- Containers related to CAM workload (t|ocloud-tcenter-cam/tcloud-tcenter-support-cam): Due to certain abnormalities, CPU utilization becomes high, exceeding 95% of the configured limit.
- Containers related to tag workload (tcloud-tcenter-platform-tag/tcloud-tcenter-platform-wtag): Due to certain abnormalities, CPU utilization becomes high, exceeding 95% of the configured limit.
- Containers related to cloud API management workload (cloud-tcenter-yunapi3): Due to certain abnormalities, CPU utilization becomes high, exceeding 95% of the configured limit.
Alarm Attributes
| Module | Name | Event Level | Manual/Automatic Clearing |
|---|---|---|---|
| Default alarm policy for tcs-pod metric monitoring | Pod CPU utilization (relative to the limit) exceeding the threshold | Level 2 alarm | Automatic clearing |
Impact on the System
No impact.
Possible Causes
- The CPU resource limit assigned to the pod is too small and needs to be increased.
- The application may have abnormalities, causing its CPU usage to increase gradually and eventually exceed the limit. The program logic needs optimization.
Processing Procedures
Check pod resource limits:
- Basic platform workload***: kubectl describe pod -n tce cloud-tcenter-xxx | grep -A 5 'Limits:'***
- Audit log workload: kubectl describe pod -n tce t|ocloud-cloudaudit-xxx | grep -A 5 'Limits:'
- CAM workload: kubectl describe pod -n tce t|ocloud-tcenter-cam/tcloud-tcenter-support-cam-xxx | grep -A 5 'Limits:'
- Tag workload: kubectl describe pod -n tce tcloud-tcenter-platform-tag/tcloud-tcenter-platform-wtag-xxx | grep -A 5 'Limits:'
- Cloud API management workload: kubectl describe pod -n tce cloud-tcenter-yunapi3-xxx | grep -A 5 'Limits:'
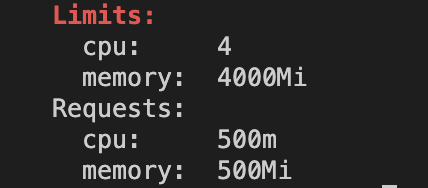
View historical monitoring information of pod:
Log in to the operation side, choose Monitoring System (CWhistle) > Cloud Product Metric > TCS/Pod, query the CPU utilization monitoring data of the Pod that triggered the alarm around the time the alarm was triggered or for a longer period, and determine whether the behavior is normal.Time Range The day of the fault Monitoring Metric pod_cpu_limit_usage Cluster global Namespace tce Pod - Basic platform workload: cloud-tcenter-xxx
- Audit log workload: Pod: t\|ocloud-cloudaudit-xxx
- CAM workload: Pod: t\|ocloud-tcenter-cam/tcloud-tcenter-support-cam-xxx
- Tag workload: Pod: tcloud-tcenter-platform-tag/tcloud-tcenter-platform-wtag-xxx
- Cloud API management workload: Pod: cloud-tcenter-yunapi3-xxx
Collect relevant information and contact the technical team for support.
